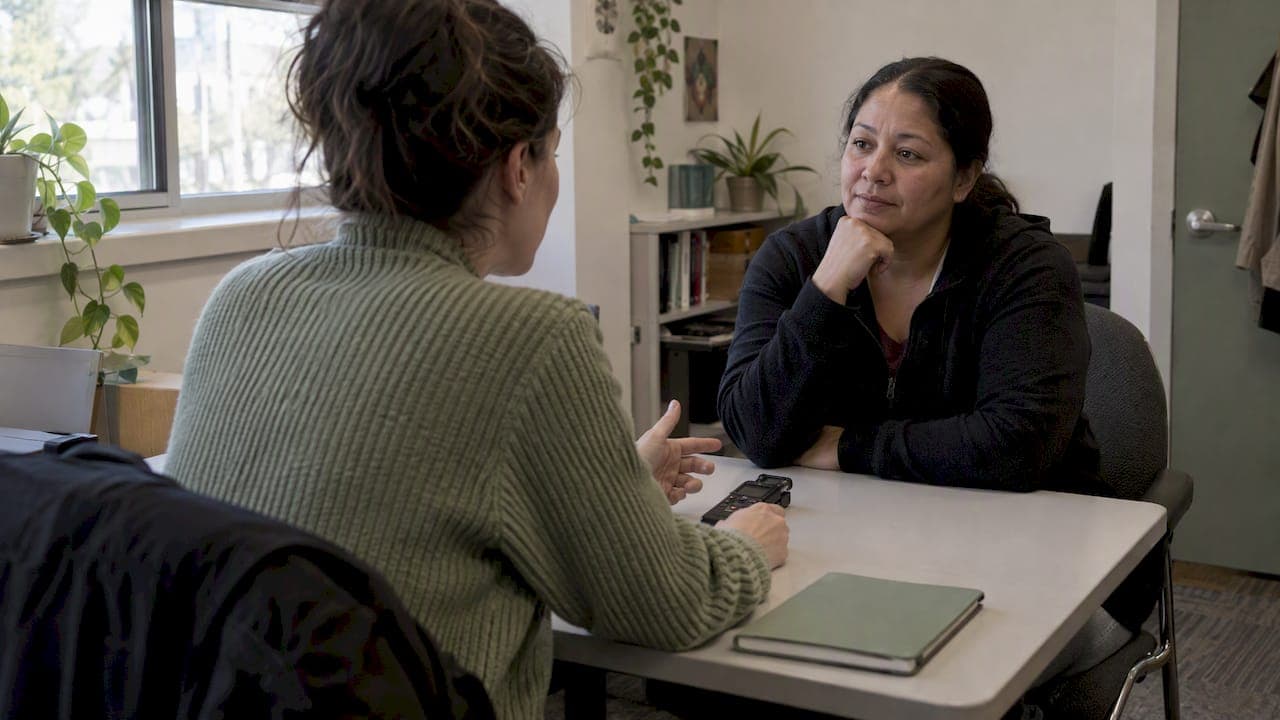
For privacy-first interview work, we recommend choosing on-device or researcher-controlled transcription whenever possible. When a cloud service or third-party transcriber is necessary, disclose that choice explicitly in consent, back it with contracts or business associate agreements, encrypt everything, limit retention, and redact content before any sharing takes place.
TL;DR:
- Use on-device or researcher-controlled transcription whenever possible to eliminate risks associated with data upload and third-party access.
- Disclose all AI or cloud transcription use explicitly in consent forms, including retention, reuse, and access policies, to ensure participant awareness.
- Match transcription method to topic sensitivity, with local or human transcription for highly confidential data, and cloud AI suitable for lower-risk, high-volume work.
- Encrypt all files at rest and in transit, set clear retention deadlines, and verify deletion to prevent unauthorized access or indefinite storage of sensitive transcripts.
- Implement independent redaction reviews and treat any publicly shared or redacted transcripts as potentially re-identifiable due to advances in de-anonymization tools.
Table of Contents
- Deciding whether to record and limiting what you collect
- Informed consent and disclosure for AI and transcription services
- Weighing on-device, cloud AI, and human transcription risks
- Securing storage, encryption, and retention throughout the transcript lifecycle
- Anonymization, redaction, and the limits of de-identification
- Sharing, ethics review, and publication safeguards
- A step-by-step workflow with sample consent language
- How on-device transcription reduces the data trail
- What practical ethics looks like when privacy comes first
- A privacy-first alternative for Apple users
- FAQ
- Sources
Deciding whether to record and limiting what you collect
The safest transcript is the one that never gets created from unnecessary data. Before pressing record, ask whether the research question actually requires audio or video, or whether structured text notes would answer it just as well. Every recording format adds a data trail: audio captures vocal tone and background sounds that can identify a location, video adds faces and visible surroundings, and continuous recording across a long session multiplies the exposure compared with short, purposeful clips.
Data minimization means treating each data point as a liability until proven useful. Timestamps, geolocation tags, and device identifiers often get captured automatically and rarely serve the research question, so turning them off at the source is more reliable than deleting them later. Capture only the channels you need: if the study is about word choice and reasoning, audio alone may suffice without video.
Giving participants real control over the session changes the risk profile too. A pause button, a clear way to ask for a passage to be struck from the record, and a short vetting window after the interview where participants can review and request edits all shift some authority back to the person being recorded, which the ethics literature around longform audio recordings treats as a core safeguard rather than an optional courtesy.
- Choose text notes over recording when the research question does not require spoken nuance.
- Favor short, targeted clips over continuous recording to reduce incidental data capture.
- Disable location and device metadata before the interview begins.
- Offer a pause or delete option during the session and a vetting window afterward.
Pro Tip: Run a two-minute sensitivity check before every interview: if the topic touches health, legal status, or relationships, default to the lowest-exposure recording method available.
Informed consent and disclosure for AI and transcription services
Consent language has to name the actual technology doing the transcribing, not a vague reference to "processing." A joint editorial on informed consent and AI transcription found that AI transcription frequently involves uploading recordings to cloud-based services, and recommended that participants be told explicitly when their words may pass through an AI system rather than a human typist.
A complete consent disclosure for transcription should cover:
- Whether audio or video will be uploaded to a cloud or AI service, and which one.
- How long the recording and transcript will be retained before deletion.
- Whether the vendor may reuse the recording to train its models.
- Who can access the raw recording and the finished transcript, and under what conditions.
- Whether an on-device or human-only transcription alternative is available on request.
- The participant's right to withdraw consent or ask that specific portions be excluded.
Sample wording that an institutional review board can adapt might read: "Your interview will be recorded and transcribed using [method]. If an AI transcription service is used, your audio may be temporarily uploaded to [vendor] and will be deleted from their servers within [timeframe]. You may request a human-only or on-device transcription instead, ask that any portion be removed from the recording, or withdraw your participation at any point before publication."
This kind of specificity does more than satisfy an ethics board. It gives participants a genuine choice rather than a blanket agreement to an undefined process, and it creates a paper trail that matches what actually happens to the recording. Researchers who skip the AI disclosure and only mention "transcription" in general terms leave themselves exposed if a participant later objects to their words passing through a third-party model they never agreed to.
Weighing on-device, cloud AI, and human transcription risks
Every transcription method carries a different risk shape, and matching the method to the sensitivity of the topic is the single most consequential decision in this AI strategy and security consulting workflow. On-device or local transcription keeps the audio and the resulting text on hardware the researcher controls, which removes the third-party exposure that comes with any upload step. The trade-off is that on-device tools depend on the device's processing power and may lag behind cloud services in raw accuracy for noisy recordings or heavy accents.

Cloud AI transcription offers speed and low cost, often transcribing an hour of audio in minutes. The risk comes from what happens after the upload: retention periods that outlast the research project, the possibility that a vendor reuses recordings to improve its models, and metadata that can leak through logs or backups the researcher never sees directly. Security guidance for automatic transcription services warns that external transcription tools often retain access to uploaded files well beyond the transcription task itself, and recommends reading vendor terms closely and requiring encryption and signed agreements before use.
Human transcribers, whether freelance or agency-based, tend to produce the most accurate transcripts for difficult audio, but accuracy comes with its own exposure. A person hearing sensitive disclosures needs a confidentiality agreement, and ideally some vetting of their track record, before they ever touch the file.
- On-device transcription minimizes third-party exposure but may trade off some accuracy on difficult audio.
- Cloud AI transcription is fast and inexpensive but introduces retention, training reuse, and metadata risks.
- Human transcribers offer strong accuracy but require signed confidentiality agreements and vendor vetting.
- Match the method to sensitivity: use on-device or human-only workflows for high-risk topics, and reserve cloud AI for low-sensitivity, high-volume work.
Scale matters too. A single sensitive interview justifies the extra effort of local transcription or a vetted human, while a hundred low-stakes interviews may reasonably use a cloud service with the right contractual protections in place.
Securing storage, encryption, and retention throughout the transcript lifecycle
A transcript needs protection from the moment the recording stops until the file is permanently deleted, not just while it sits in a cloud account. Encryption at rest and in transit is the baseline: files should never sit unencrypted on a laptop, shared drive, or USB stick, and transfers between devices or to a vendor should run over encrypted channels with keys managed separately from the data itself.
- Encrypt every recording and transcript at rest and in transit, and store encryption keys apart from the files they protect.
- Apply least-privilege, role-based access so only people who need the transcript for their specific task can open it, and log who accessed what and when.
- Set a retention schedule tied to the research protocol, then verify deletion actually happens, including in backups and vendor systems, rather than assuming it does.
- Require a business associate agreement or written confidentiality agreement before any external vendor or transcriber touches the recording.
Institutional guidance on using transcriptionists for recorded interviews recommends documenting exactly who will have access, where recordings are stored, and when they will be destroyed whenever an external transcriptionist is involved, and provides a sample confidentiality agreement researchers can adapt directly. Ownership also matters here: provider confidentiality guidance notes that transcription vendors act as processors rather than owners of the content, meaning the research team retains authority over how transcripts get reused even after a vendor has handled the file.
Access logs deserve ongoing attention rather than a one-time setup. A quarterly review of who still has access to older project files catches the common failure mode where a research assistant's account stays active long after their role on the project ended.
Pro Tip: Tag every transcript file with its retention deadline at the moment it is created, so deletion becomes a scheduled task rather than something you have to remember months later.
Anonymization, redaction, and the limits of de-identification
Pseudonymization, redaction, and aggregation solve different problems and get confused often enough to create false confidence. Pseudonymization swaps a name for a code while keeping the underlying structure intact, which means a sufficiently motivated reader can sometimes still work backward from context. Redaction removes the identifying detail outright, cutting a name, employer, or location from the transcript text. Aggregation reports findings only at the group level, never quoting an individual passage closely enough to trace it back.
A defensible redaction workflow follows a few steps: a first pass by the researcher who conducted the interview, a second independent pass by someone else on the team who did not conduct it, and a final check against the original audio to confirm that indirect identifiers, like a rare job title or a distinctive personal story, got caught along with the obvious names and places.
- Pseudonymize when you need to track the same participant across multiple data points without using their real name.
- Redact when a detail could identify the person even without their name attached.
- Aggregate when individual quotes are not necessary to make the research point.
- Use independent, second-pass review rather than trusting a single redaction pass.
A small-scale proof-of-concept found that widely available large language models could partially re-identify anonymized interviews that researchers had released after standard redaction. The finding matters because it shows that redaction considered sufficient under older standards may not hold up against tools that can now cross-reference writing style, phrasing, and contextual detail at scale. The practical response is governance, not panic: treat any publicly released transcript as potentially re-identifiable, avoid releasing full transcripts for highly sensitive topics even when redacted, and favor aggregated findings or supervised access over open publication when the subject matter carries real risk to participants.
Sharing, ethics review, and publication safeguards
Institutional review boards typically expect a protocol that specifies the transcription method, who will have access to raw recordings, how long they will be retained, and what redaction standard will apply before any excerpt leaves the research team. Consent language should mirror these same details rather than describing them only in the protocol, since participants only see the consent form.
Confidentiality agreements and business associate agreements for transcribers or vendors should spell out data handling obligations clearly: where files are stored, who can view them, how long they are kept, and the exact destruction method once the engagement ends. These documents are not boilerplate. A missing clause on subcontracting, for instance, can leave a path open for a vendor to pass audio to a third party without the research team's knowledge.
Sharing does not have to be all-or-nothing. Tiered approaches let researchers calibrate exposure to sensitivity:
- Vetted excerpts reviewed by participants before any quote appears in a publication.
- Supervised access, where outside researchers view full transcripts only within a controlled environment rather than downloading them.
- Embargoes that delay public release of raw data until enough time has passed to reduce identification risk.
Before submitting transcripts to a repository or attaching them to a publication, confirm that consent language explicitly covered this kind of sharing, that redaction has passed independent review, that any required confidentiality agreements are on file, and that the retention and destruction schedule for the original recordings still matches what participants were told.
A step-by-step workflow with sample consent language
Turning these principles into a repeatable process keeps privacy protections consistent across a project rather than reinvented for every interview.
- Pre-interview: Run a sensitivity assessment on the topic, choose the least-exposing transcription method that still meets the research need, and draft consent language naming that method explicitly.
- During the interview: Give participants pause and delete controls, and disable unnecessary metadata capture like geolocation before recording starts.
- Post-interview: Transfer the recording over an encrypted channel, transcribe it using the disclosed method, apply redaction with independent review, tag the file with its retention deadline, and log who accesses it afterward.
A short consent excerpt that covers the essentials:
A one-page checklist for an institutional review board submission should confirm: the transcription method is named in consent, retention periods are specified, redaction procedures are documented, confidentiality agreements are on file for any external vendor, and access logs exist for anyone who touches the raw recording or transcript.
How on-device transcription reduces the data trail
On-device transcription processes the recording directly on the researcher's own hardware, so the audio never leaves the device to reach a remote server. This removes an entire category of risk from the threat model: there is no upload to intercept, no vendor retention policy to track, and no training-reuse question to resolve, because the data simply does not travel.
The trade-off is platform dependency. On-device tools are tied to the device and operating system they run on, so availability and performance depend on the hardware a researcher already owns, and teams working across mixed device fleets may need a hybrid approach. Even so, offering an on-device option alongside cloud and human alternatives in the consent form gives participants a meaningful choice rather than a single predetermined path, which fits directly into the disclosure practices described earlier in this guide.
What practical ethics looks like when privacy comes first
We think the gap between a privacy policy and privacy practiced in the room is where most research ethics actually gets tested. Consent forms that name the transcription method and offer a genuine opt-out tend to earn more candor from participants, not less, because people can tell when they are being given real control versus a formality. The failure mode we see most often is not malicious. It is researchers defaulting to whatever transcription tool is fastest and backfilling the consent language afterward. Scaling protections to the sensitivity of the topic, rather than applying one template to every project, is the habit that actually holds up.
— Alex
A privacy-first alternative for Apple users
For researchers who want the on-device option discussed throughout this guide without building a custom workflow, we build Echo Chamber Pro specifically for that purpose. Recordings and transcriptions are processed entirely on the Apple device running the app, so audio never has to travel to a remote server to become text.
- Transcription happens locally, which removes the upload step that drives most of the cloud-related risks covered in this guide.
- Designed to work on Apple devices, fitting naturally into workflows centered on iPhone or iPad.
- No mandatory account or hidden data transfer: network connections are optional and clearly explained.
The app is available via monthly, yearly, or one-time purchase options; current pricing details are on the pricing page. If your research involves sensitive topics and you already work on Apple hardware, it is worth a look as the on-device leg of your transcription options.
FAQ
Is it legal to record an interview without consent?
Recording laws vary by jurisdiction and by whether all parties or only one party must agree to the recording, so the safest approach is always to obtain explicit consent before recording rather than relying on a jurisdiction's minimum legal requirement. Research settings typically require documented informed consent regardless of what local recording law technically permits.
Is it legal to record meetings using AI transcription tools?
Using AI transcription tools generally requires the same consent as any other recording, plus disclosure that an AI or cloud service will process the content, since that detail affects what participants are agreeing to. A joint editorial on AI transcription recommends explicit disclosure whenever recordings may be uploaded to an AI-based service.
Will transcriptionists be replaced by AI?
AI transcription has become faster and cheaper, but automated transcripts still often need human review to catch errors, which keeps a human-in-the-loop step relevant for accuracy rather than eliminating the role outright. A mixed-mode interview study used automated transcription followed by human validation, showing the two approaches working together rather than one fully replacing the other.
How should interview transcripts look?
A well-formed interview transcript identifies speakers consistently, preserves meaningful pauses or nonverbal cues when relevant to the research question, and flags any redacted or removed content clearly rather than silently deleting it. Formatting should also note the transcription method used, since that detail matters for later privacy and accuracy review.
Sources
For deeper guidance on the standards referenced throughout this piece, we point readers to the NIST Privacy Framework for risk management categories, the research on longform recording ethics for participant-control practices, and institutional guidance on vendor confidentiality agreements for transcription projects.